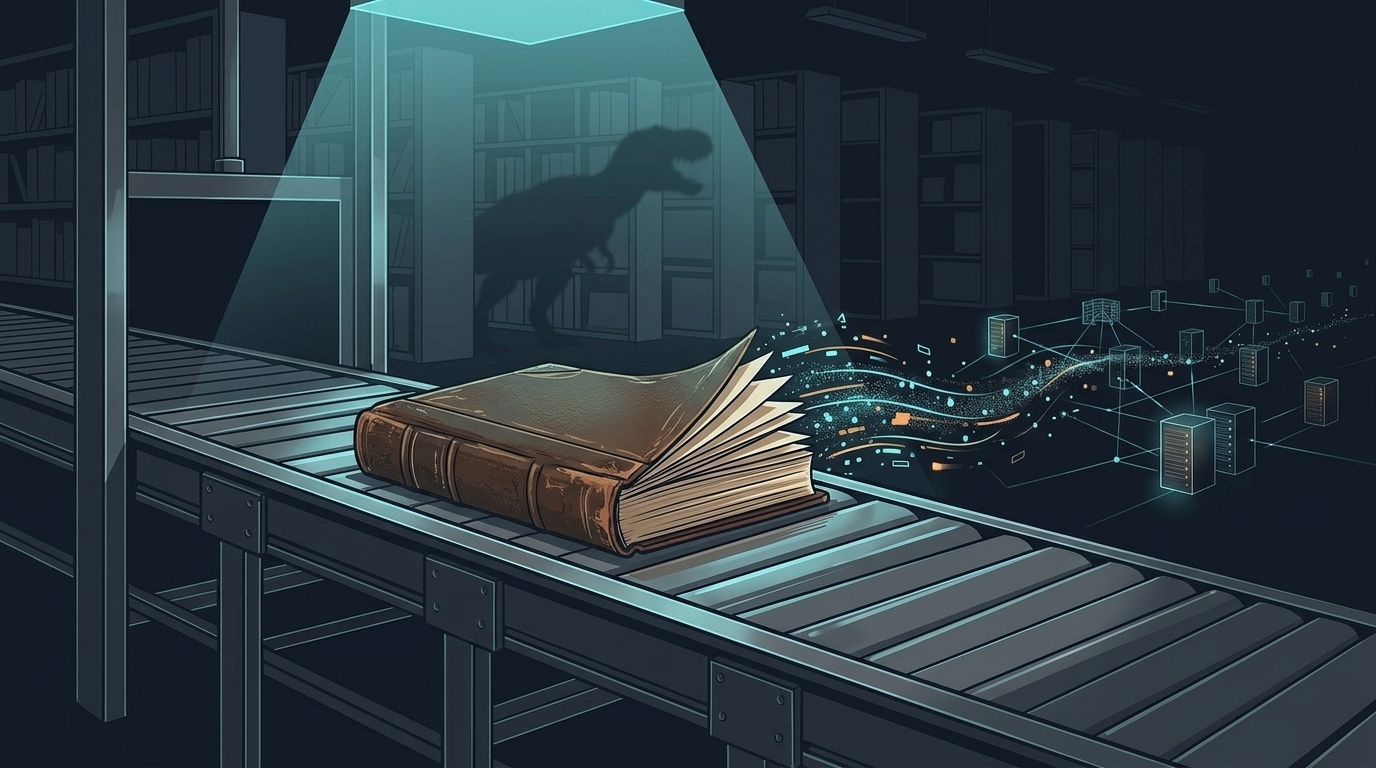
Amazon began as the company that made it easier to buy a book. Its AI operation has apparently found a more efficient relationship with them: buy them by the thousand, cut off their spines, scan the pages, and throw the bodies away.
That is the picture in 404 Media’s investigation, which planted a tracker in a rare book and followed it to an Amazon facility in Las Vegas. Workers there described receiving large shipments, removing bindings, and scanning the pages. Amazon did not deny buying books; it said it purchases them through commercial channels to improve products and services.
The detail that should outlive the obligatory dystopian jokes is not the AirTag. It is the incentive. The AI data hunt has moved beyond the open web and into material that was scarce precisely because nobody had bothered to put it online. Once that happens, a book is no longer a book in the buyer’s model. It is an unindexed text object with an ISBN and a useful absence of prior training.
The library has become a quarry.
The web was the cheap part
For years, the industry sold training data as an internet problem: crawl broadly, negotiate late, litigate when necessary. That model had a built-in convenience. The source material was already digitised, searchable, and—at least from a scraper’s perspective—lying around.
The more useful text becomes harder to find. TechCrunch notes why old and obscure books are attractive: they contain text that is not already ubiquitous online and, being published long before the generative-AI boom, cannot be model-written sludge fed back into the machine.
That does not make destructive scanning inevitable. Libraries digitise fragile works without treating the original as industrial packaging. The difference is not technical capability. It is ownership and incentive. A preservation project wants the source to remain available. A model builder gains a competitive input by absorbing the source into weights nobody else can inspect, reuse, or even reliably know existed.
The backlash is therefore not nostalgia for paper. In the Reddit discussion cited by Ars Technica, even people who dismissed the books as dust-collectors landed on the same uncomfortable question: if a little-known edition is scanned into a private model and then destroyed, has access expanded—or has a public object become a private capability?
An LLM can emit a fragment of knowledge. It cannot replace the source, its physical context, or the ability to check what it actually said. “We made it more accessible” is doing heroic work when the resulting access is probabilistic, metered, and owned by the company that consumed the original.
Bankruptcy is the next shelf
The same week supplied a second, less visual, version of the story. Google won a bankruptcy auction for part of Spirit Airlines’ enterprise dataset: about 100 million emails, 500 million Teams chats, and business records, for $10 million, pending court approval. Google says it will receive no personal information and that a third party will rigorously scrub the data before receipt.
Take that assurance seriously, but do not mistake it for the whole question. The asset is valuable because it contains years of work in its natural habitat: operational arguments, handoffs, decisions, exceptions, documents, and organisational language. That is precisely the stuff a model trained on generic web prose does not get for free.
Bankruptcy law has long been good at turning a failed company into saleable parts. In the AI era, its accumulated memory may become one of those parts. The employees, suppliers, and customers whose work produced that memory may have no meaningful say in where its residue goes next, even if identifiers are removed.
This is not a claim that Google’s purchase is improper or that de-identification is meaningless. It is a warning about the direction of travel. When a company fails, its fleet, leases, and office furniture are visibly liquidated. Its institutional exhaust can now be bid on as model fuel. The auction notice is becoming a data pipeline.
A supply chain needs custody, not just consent forms
The industry will answer that buyers are using lawful channels. They may be. Lawful acquisition is a floor, not a public-interest test.
What is missing is provenance that survives extraction. Which works were scanned? Were they destroyed? Could a library or rights holder flag an irreplaceable copy before it enters an opaque pipeline? What enterprise archives can be sold for training? What does “de-identified” mean when the material captures the texture of real work rather than a row in a database? And who is responsible when the answer to all of those questions is a press statement after the truck has left?
These are not anti-AI questions. They are the questions one asks when a new industrial appetite meets finite cultural and institutional stock. We know how to build supply chains for timber, pharmaceuticals, conflict minerals, and hazardous waste. They are imperfect, but at least they begin with the premise that inputs have histories and extraction has consequences.
Training data still enjoys the fantasy version: if the text can be bought, scraped, or auctioned, the story ends there. It does not. The most revealing symbol in the Amazon report is the dinosaur logo on the warehouse door, holding a book in its teeth. It is almost too on the nose. Almost.
The next battle over AI data will not be about whether models need more of it. They plainly do. It will be about whether the institutions feeding them are required to leave anything behind.