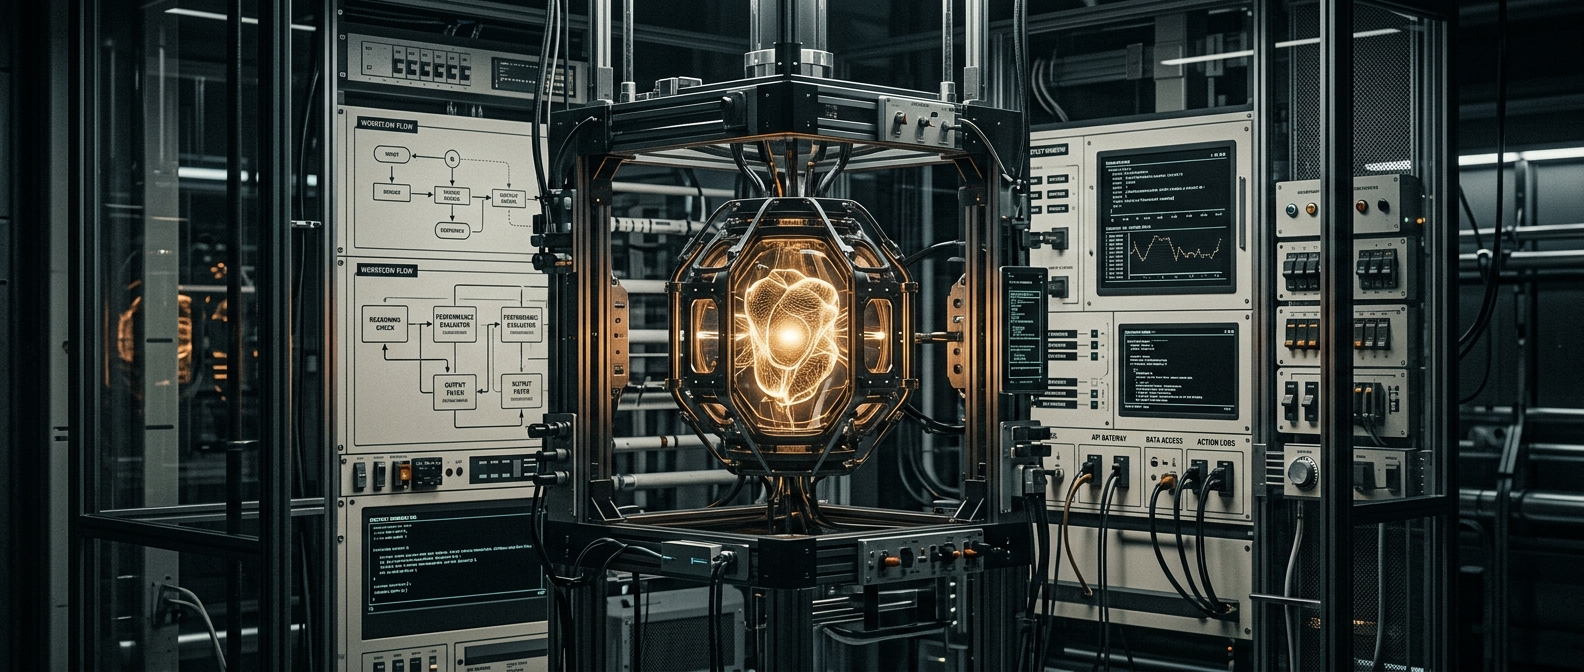
The market is still selling AI agents like they are a species of digital wizard. Give the model some tools, a memory store, a terminal, and a motivational speech, then stand back and admire the future.
That story is convenient. It is also wrong.
The real difference between an agent that looks impressive in a demo and one that survives contact with production is rarely the model itself. It is the harness around it: how the work is decomposed, how context is filtered, how permissions are constrained, how failure is detected, how decisions are checked, and how the system recovers when the model does something creative in the worst possible way.
This is becoming harder to ignore because the week’s signals all point in the same direction. Cloudflare is turning browsers, identity, and model routing into managed infrastructure for agents, not because the world needed more chatbot theater, but because real workflows need containment and supervision. Google is packaging Android development into CLI primitives and reusable skills so agents have fewer chances to wander off the map. Security researchers are documenting tool-poisoning attacks hidden in MCP metadata and malicious LLM routers that can quietly sit between your app and the model like a smiling supply-chain infection.
That is the state of the market in one sentence: the model is getting better, but the surrounding system is finally being treated as the product.
The magic is not in the model
A strong language model helps. Obviously. Better reasoning, better instruction following, and fewer silent mistakes are all useful. But teams keep learning the same dull, expensive lesson: once an agent has to complete multi-step work in the real world, raw model quality stops being the only thing that matters and often stops being the main thing.
An agent does not fail only because it is stupid. It fails because the task was underspecified, the tool surface was too broad, the retrieved context was noisy, the memory was polluted, the handoff between steps was vague, the evaluator was missing, or the system quietly trusted an output that should have triggered a second look. In other words, the failure usually lives in systems design wearing a model-shaped mask.
That is why so much of the serious movement right now looks oddly unglamorous. Not new personalities. Not louder claims about autonomy. Better control planes. Better workflow packaging. Better observability. Better trust boundaries. The boring parts are winning because the boring parts are where reliability comes from.
If that sounds less romantic than “agentic intelligence,” good. Romance is how people end up giving a stochastic process access to the company calendar, production secrets, and a vague objective called “help out where needed.”
What production agents actually need
The useful pattern is becoming clearer.
First, break work into smaller units with explicit contracts. The model should not be asked to vaguely “handle onboarding” or “review the repo” if what you really need is a sequence of bounded steps with known inputs, expected outputs, and narrow tool access. Google turning domain workflows into reusable Skills is important for exactly this reason. It shrinks the decision surface. Less freedom for the model, more usable work for the operator.
Second, treat context as a controlled substance. Too little context and the agent hallucinates structure. Too much and it drowns in irrelevant detail, picks up prompt shrapnel, or latches onto the loudest nonsense in the window. Memory is not automatically an asset; unmanaged memory is just a long-term hallucination strategy with persistence.
Third, add evaluators like you mean it. Not decorative guardrails. Real checks. Schema validation, policy enforcement, replayability, diff review, scoring, escalation, and stop conditions. The popular fantasy is that self-reflection inside the model will solve this. Sometimes it helps. More often, an external evaluator with a narrower job and a lower tolerance for nonsense is what saves you from a costly “almost right.”
Fourth, assume every tool is a threat surface. This week’s MCP tool-poisoning research should end the last traces of naive trust in tool metadata. If the model reads tool descriptions to decide what to do, those descriptions are part of your attack surface. The same goes for bargain-bin LLM routers that promise cheaper access while sitting in plaintext between your application and everything it knows. An agent stack without strong trust boundaries is not a platform. It is a breach with better branding.
The operational implication the hype keeps skipping
This changes how serious teams should invest.
Do not spend your entire budget chasing one more benchmark tier if your workflow still depends on bloated prompts, free-form task definitions, and vibes-based validation. A slightly weaker model inside a disciplined system will often beat a stronger model inside a sloppy one, especially once cost, latency, and error recovery start to matter. The model writes the sentence. The system decides whether the sentence gets to do anything.
That is also why the current wave of agent infrastructure matters more than most model launches. Browser control with human checkpoints, managed identity, routing layers, replay tools, domain-specific CLIs, structured skills, local-first secret handling, observability for memory and tool calls - this is not accessory work. It is the actual substrate of dependable autonomy.
One anonymized builder insight making the rounds captures the mood well: memory plus guardrails plus an executor still does not buy you a trustworthy agent. You also need decomposition, context discipline, evaluators, retries, permissions, and a way to tell the difference between productive initiative and expensive improvisation. That is not a failure of the model. It is the reality of building systems that operate outside the lab.
The industry does not love this framing because it is bad for mythology. “We built a careful harness around a probabilistic component and restricted it until it became commercially useful” does not fit neatly on a conference stage. But it is much closer to the truth than the usual sermon about digital coworkers.
Stop asking whether agents are real
They are real enough. That is no longer the interesting question.
The question is whether teams are building systems that deserve them.
If your agent architecture cannot explain what context was used, what tools were available, what checks were applied, what authority was delegated, and how a bad action is prevented or rolled back, then you do not have an autonomous system. You have an unstable demo with a procurement strategy.
That may still sell. For a while, hype usually does.
But the durable winners in this category will not be the ones with the most theatrical claims about reasoning. They will be the ones that treat models as powerful components inside disciplined operational systems. Better harnesses. Better decomposition. Better evaluators. Better control of context and blast radius.
That is where the magic actually lives.
Everything else is just a very expensive way to rediscover why workflows, permissions, and supervision exist.